Webhook Alerts for Monitoring: A Developer's Guide to Routing Uptime Alerts Into Your Own Systems
18 min read
Loading...
Webhook alerts push real-time monitoring events straight to an endpoint you control, so your systems can act on downtime instantly instead of waiting for someone to read a Slack message.
If you've ever received a Slack ping at 2am about a downed API and thought, "great, now I have to manually open a ticket, restart the service, and update the status page myself" — you already understand the problem webhooks solve. Instead of a notification that just sits there waiting for a human, a webhook lets your monitoring platform send structured data directly to an endpoint you own, triggering automated workflows the moment something changes. With Moonitor, that means check failures, SSL expiry warnings, and missed cron jobs can land in your incident system, custom dashboard, or internal API within seconds — no polling required.
That's the short version. But if you're the person actually wiring this up, you want to know what the payload looks like, how to secure the endpoint properly, and what to do when a delivery silently fails at the worst possible moment. So let's get into it — with actual code, not just concepts.
Email and Slack alerts are wonderful — for humans. They're readable, they show up on your phone, and they don't require you to write a single line of code. But here's the catch: a human still has to do something with that information. Someone has to read the message, decide it's real, open a ticket, and maybe ping the on-call engineer. That's fine at 2pm on a Tuesday. It's a lot less fine at 2am when nobody's watching the channel — and if your team runs UK hours with on-call cover overnight, you know exactly how thin that coverage can get.
Webhooks skip the human-in-the-loop step. Instead of "hey, something's wrong," you get structured JSON your systems can parse and act on immediately. That single difference opens a lot of doors:
This becomes especially valuable once you're running more than a handful of checks. If you're doing HTTP/S, port, SSL, DNS, and cron job monitoring across dozens of services, a single Slack channel turns into noise fast. Webhooks let you route different alert types to different systems — SSL expiry warnings to your certificate renewal pipeline, cron job failures to your ops dashboard, and DNS changes to a security review queue — without anyone triaging manually. The monitoring API rounds this out nicely too, since it lets you pull historical context the moment a webhook fires, rather than relying on the alert alone.
Once you've decided webhooks are the way to go, the next question is: what actually shows up in that POST request? A quick disclaimer first — the example below shows the shape of a typical monitoring webhook payload, not a frozen specification. Field names, exact types, and available metadata vary between providers and can change over time, so always check your monitoring platform's current documentation before you build a parser against it.
Most mature monitoring platforms structure payloads around two ideas — an event envelope (metadata about the alert itself) and an incident payload (details about what actually happened). A generic example typically includes something like:
Here's an illustrative “down” alert — again, treat this as a generic example rather than an exact Moonitor schema:
{
 "event_id": "evt_8f2ab1",
 "monitor_id": "mon_7c19",
 "monitor_type": "http",
 "status": "down",
 "timestamp": "2025-01-15T10:00:02Z",
 "verified_regions": ["eu-west", "us-east"],
 "response_time_ms": null,
 "error": "Connection timed out after 10000ms"
}
And a matching recovery event:
{
 "event_id": "evt_8f2ab2",
 "monitor_id": "mon_7c19",
 "monitor_type": "http",
 "status": "up",
 "timestamp": "2025-01-15T10:04:47Z",
 "response_time_ms": 312,
 "error": null
}
If your platform supports multi-region failure verification, you'll often see a verified_regions field on the down event — that's designed to stop a single flaky probe from paging someone over a network blip. The exact confirmation logic (how many regions and how much delay) varies by provider and plan, so it's worth confirming in your dashboard settings rather than assuming.
One genuinely useful thing to look for is whether the payload structure stays consistent across monitor types. Whether it's an SSL certificate nearing expiry or a cron job that missed its heartbeat, if the same envelope fields show up in the same places across HTTP, keyword, port, ping, SSL, cron/heartbeat, and DNS checks, you can write one parsing function instead of seven. That consistency — when it holds — saves you a genuinely annoying amount of future debugging. Just confirm it holds for your specific setup before you build around the assumption.
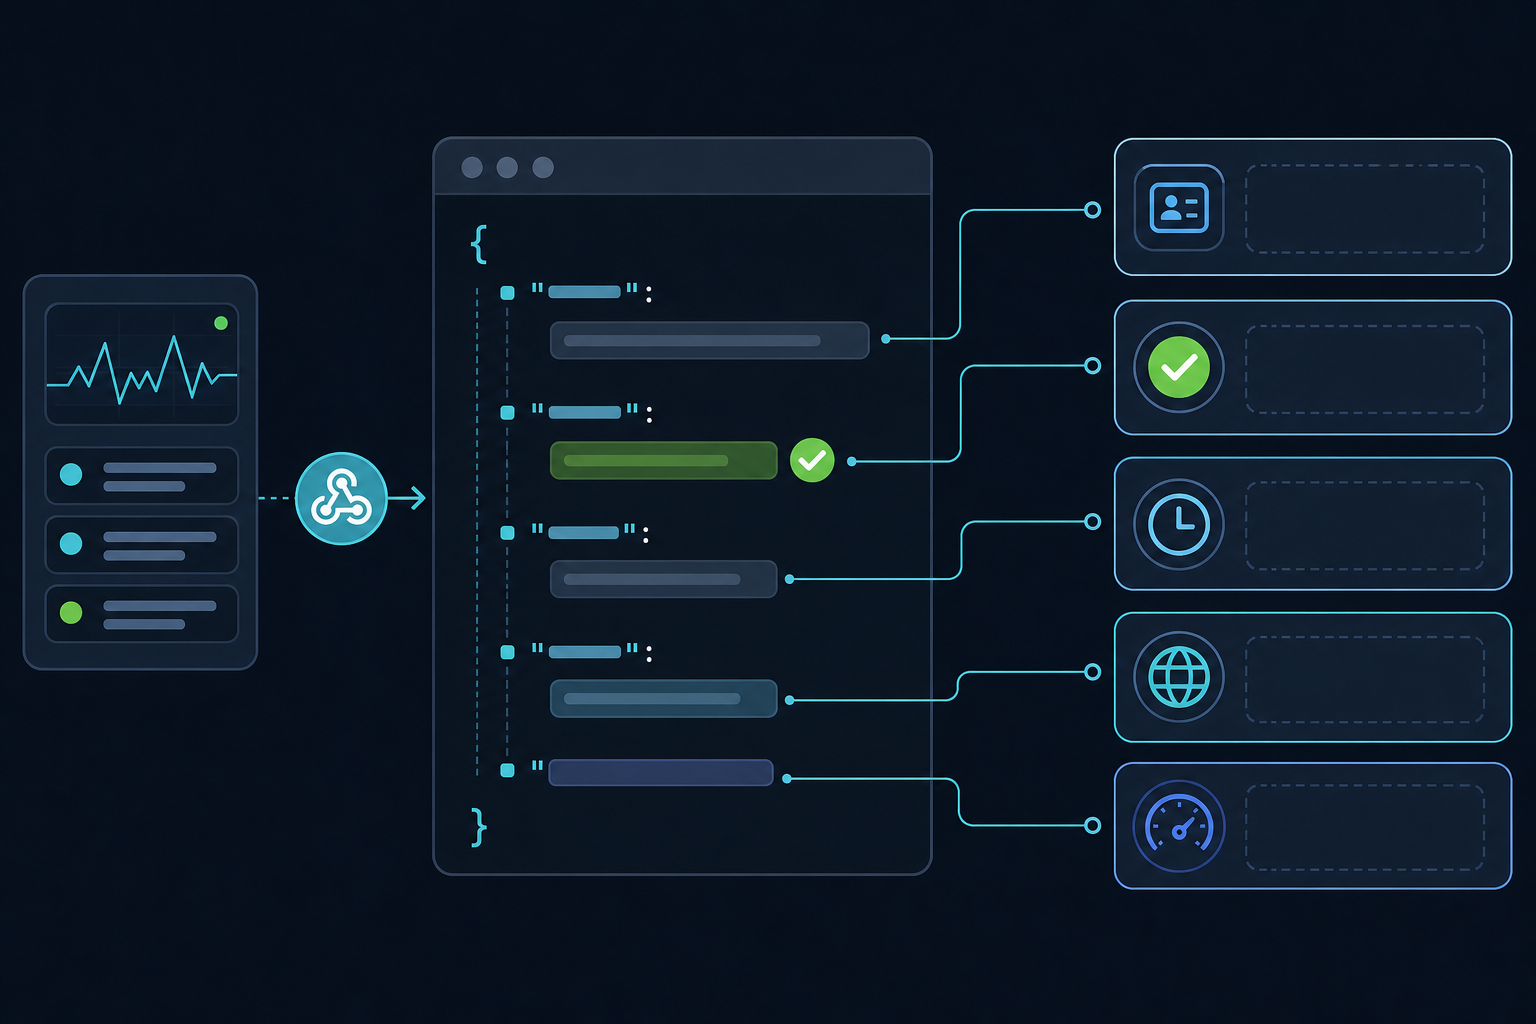
Getting a webhook running usually takes less time than reading this section. I'll break it into four stages so it's easier to follow along.
1. Create the endpoint. Stand up something that accepts POST requests — a serverless function, a route on your existing API, or a temporary tool such as a request-inspecting webhook site while you're testing. Here's a minimal example in Node.js/Express that verifies a signature, deduplicates by event ID, and responds quickly:
const crypto = require('crypto');

function verifySignature(rawBody, signatureHeader, secret) {
  const expected = crypto
    .createHmac('sha256', secret)
    .update(rawBody)
    .digest('hex');
  return crypto.timingSafeEqual(
    Buffer.from(expected),
    Buffer.from(signatureHeader || '', 'utf8')
  );
}

app.post('/webhooks/monitoring', express.raw({ type: 'application/json' }), async (req, res) => {
  const signatureHeader = req.headers['x-webhook-signature']; // confirm the actual header name in your platform's docs

  if (!signatureHeader || !verifySignature(req.body, signatureHeader, process.env.WEBHOOK_SECRET)) {
    return res.status(401).send('invalid signature');
  }

  const payload = JSON.parse(req.body);

  if (await alreadyProcessed(payload.event_id)) {
    return res.status(200).send('duplicate, ignored'); // idempotency check
  }

  await markProcessed(payload.event_id);
  res.status(200).send('ok'); // acknowledge quickly, then do the heavy lifting

  enqueueForProcessing(payload);
});
Note: confirm the exact signature header name, hashing algorithm, and any timestamp tolerance your platform uses before relying on this in production — treat the above as a starting pattern, not a guaranteed specification.
2. Configure Moonitor. Add the webhook URL in your alert settings. You can use it alongside email, Slack, Discord, or Telegram, or as your only channel — that's entirely up to how your team works. Choose which monitors and status changes trigger it; you might only want webhooks for production API monitoring, while development environment checks stay on Slack.
3. Test the delivery. Send a test alert from your dashboard, or simulate one yourself with curl while you're building:
curl -X POST https://your-endpoint.example.com/webhooks/monitoring \
  -H "Content-Type: application/json" \
  -H "X-Webhook-Signature: <test-signature>" \
  -d '{"event_id":"evt_test123","monitor_id":"mon_test","status":"down"}'
This confirms your field names match what you expected and that your parser doesn't choke on unexpected data.
4. Make processing reliable. Confirm your endpoint returns a 2xx response quickly — within a few seconds is a safe target, though check your platform's documentation for the exact timeout it enforces. If your endpoint doesn't respond in time, most platforms will treat the delivery as failed and may retry, which is exactly why the idempotency check above matters: you want duplicate deliveries to be harmless, not disruptive.
This last step trips people up more than you'd think. It's easy to build an endpoint that processes the alert perfectly but forgets to send back a 2xx status code because it's busy doing asynchronous work first. Return the response quickly, then handle the heavy lifting afterwards — that's what the queue call in the code above is doing.
This is where webhooks stop being a notification mechanism and start being infrastructure. Once alerts are structured JSON hitting an endpoint you control, you can route them almost anywhere:
That last pattern — webhook plus API lookup — is genuinely one of the most useful things you can build. The webhook tells you what just happened. The API tells you what usually happens. Together, they give whoever's on call enough context to make a decision in seconds instead of digging through a dashboard.
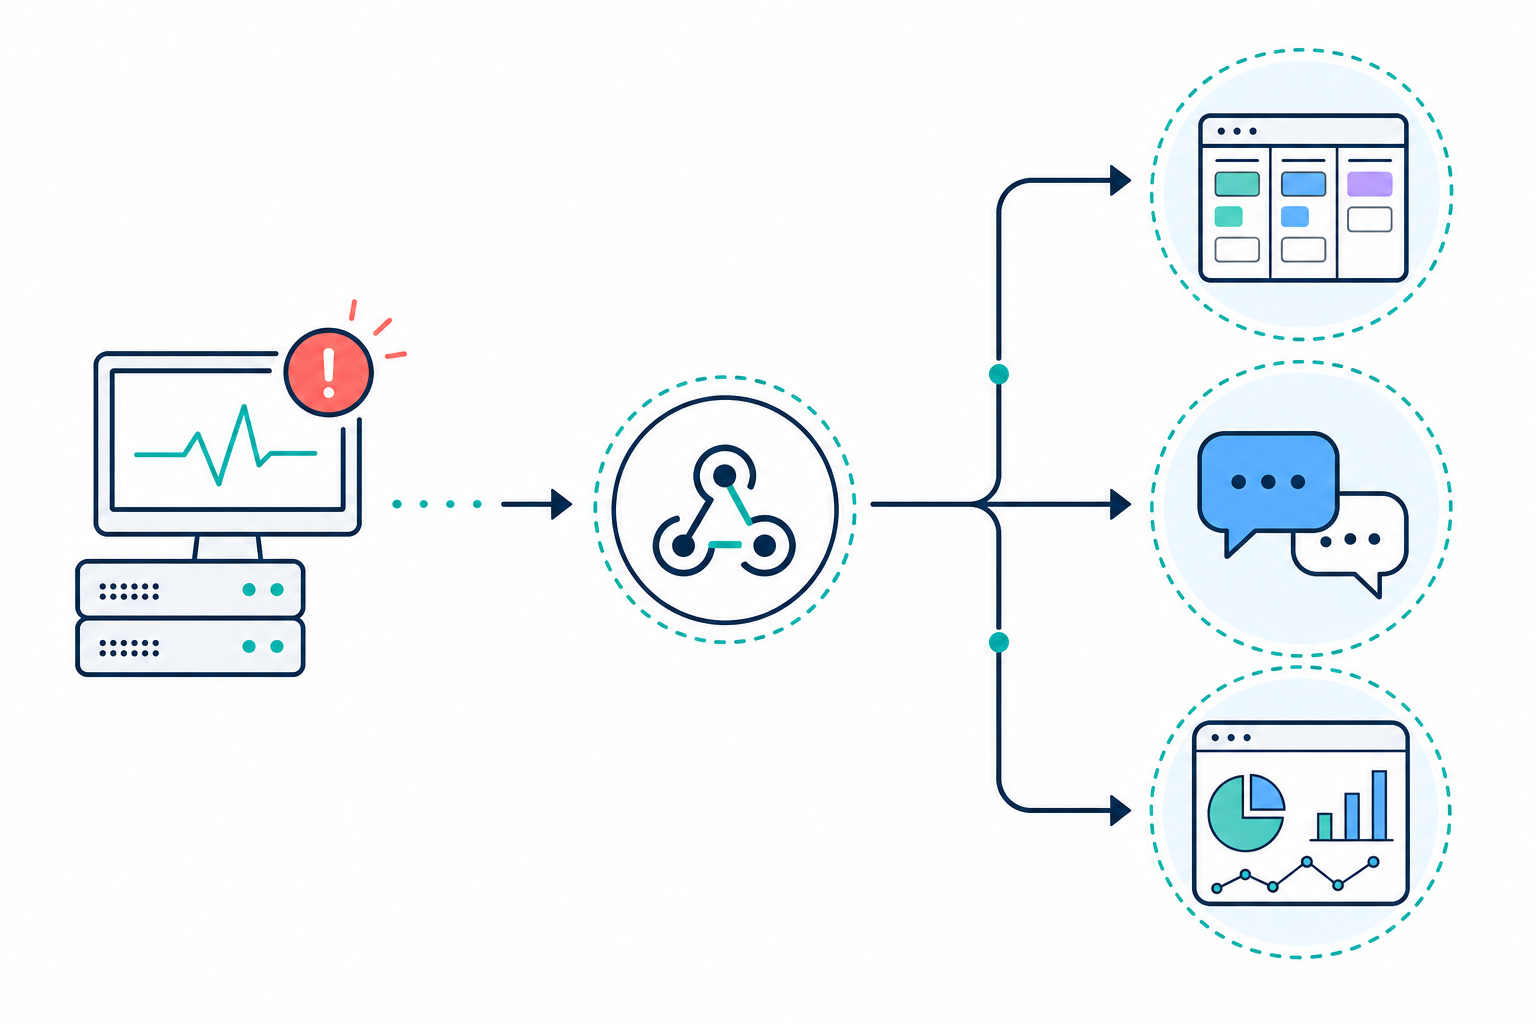
Here's the part people skip until something goes wrong. A webhook endpoint is, by definition, a public-facing URL that accepts incoming data and often triggers automated actions. That's exactly the kind of thing you want to lock down properly — and if your payloads ever touch anything resembling personal or customer data, it's worth thinking about this through a UK GDPR lens too: know where that data is logged, how long you retain it, and who can access it.
One subtlety worth internalising: webhook delivery from most platforms is generally at-least-once, not exactly-once — meaning duplicate deliveries can and do happen, often from a temporary network blip on either end triggering a retry. That's exactly why the event_id deduplication check in the earlier code sample matters. Store the event ID and check for duplicates before you trigger anything irreversible, such as opening a second ticket for the same incident or restarting a service that's already mid-restart. If you're unsure of your platform's exact retry count or backoff schedule, that's worth confirming in the documentation — build your idempotency handling to be safe regardless.
Even a well-built webhook setup will occasionally hiccup, so it helps to have a debugging routine ready before you need it. Here's a quick symptom-to-cause table I keep coming back to:
| Symptom | Likely cause | What to check |
|---|---|---|
| No request ever arrives | Wrong URL configured, DNS issue, or firewall blocking inbound traffic | Confirm the URL in your alert settings; check firewall/WAF logs for blocked requests |
| 401/403 response | Signature mismatch, rotated secret, or signing against parsed rather than raw body | Compare the raw request body against what you're hashing; confirm the secret matches what's configured |
| Timeout (408/504) | Endpoint doing synchronous heavy work before responding | Move processing to a queue and return a 2xx immediately, as shown earlier |
| 429 rate limited | Retry storm hitting a rate-limited endpoint | Check for repeated retries and add backoff handling on your side |
| Same event processed twice | Missing idempotency check | Confirm you're storing and checking event_id before side effects |
Beyond that table, it's worth building this into a habit:
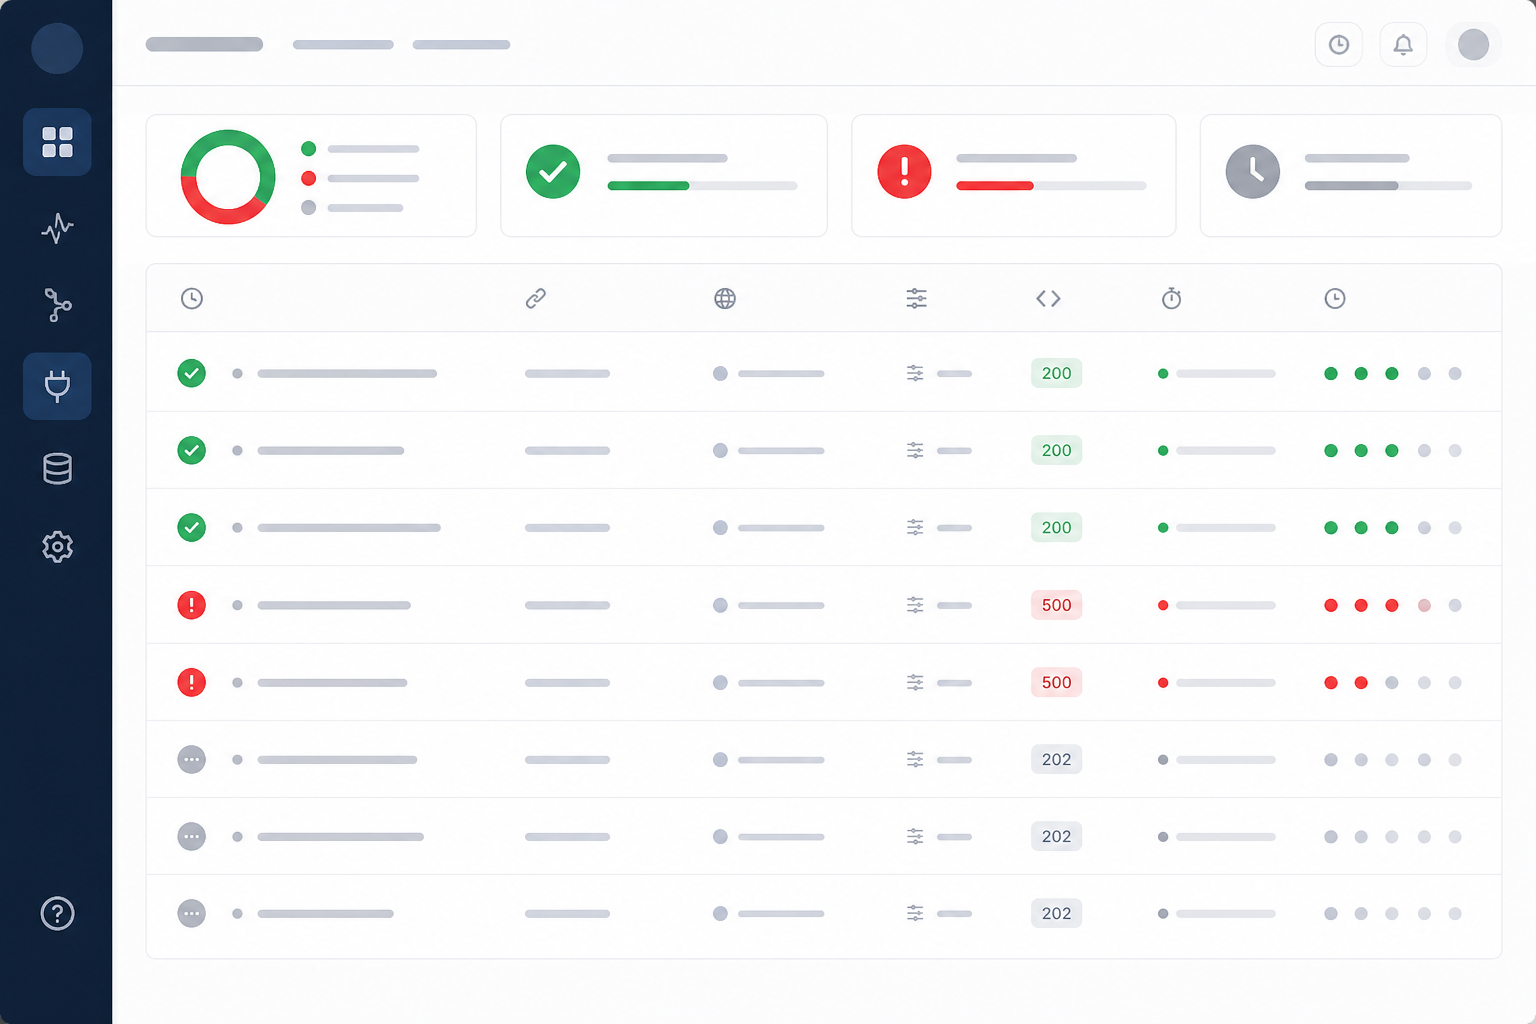
Webhooks and the monitoring API solve two different problems, and the best setups use both. Webhooks push data to you in real time — you don't ask, they just arrive the moment something changes. The monitoring API, on the other hand, lets you pull historical incident data, response-time analytics, and monitor configuration whenever you need it.
Think of it this way: the webhook tells you an incident just started. The API lets you ask, “how long has this monitor been flaky this month?” or “what's the average recovery time for this service?” That's incredibly useful for backfilling context the instant a webhook fires, or for building your own reporting layer that goes beyond what any built-in dashboard offers. Just keep pagination and rate limits in mind when you're pulling larger historical ranges — most APIs cap how much you can request per call, so plan for looping through pages rather than one giant fetch. Reconciling API results against webhook events by event_id or monitor_id also helps you catch any gaps between what was delivered and what actually happened.
It also matters for a less obvious reason: portability. Access to your uptime history, SSL certificate timelines, and cron job records through an API means that data can live in a format you control, not only inside someone else's UI — though it's worth checking your specific plan for what's included in exports, how far back retention goes, and in what format. If you ever need to migrate, audit, or build custom reporting, knowing the real scope of that portability before you need it saves a lot of stress later, particularly if data residency or audit requirements are part of your compliance picture.
How do I receive monitoring alerts in my own system via webhook?
Add your endpoint's URL to your monitoring platform's alert settings, choose which monitors and status changes should trigger it, then send a test alert. Moonitor will POST a JSON payload to that URL when a monitored check changes state, so your system receives the alert in near real time. Always confirm your endpoint returns a fast 2xx response, and check your platform's documentation for its exact retry and timeout behaviour.
What does a typical webhook payload look like?
Most monitoring webhook payloads include a monitor ID and type, the current status (up or down), a timestamp, response time, and an error message if applicable — some platforms also include which region verified a failure. Treat any example payload as illustrative rather than a fixed schema, and check your platform's current documentation for the exact fields it guarantees.
How do I secure a webhook endpoint from abuse?
Use HTTPS, verify each request with a shared secret or HMAC signature checked against the raw request body, and restrict the endpoint to expected source IPs where possible as an extra layer. Rate-limit and validate incoming payloads before your system processes them, and never trust alert fields enough to pass them unvalidated into commands, queries, or internal URLs.
What happens if my webhook receives the same alert twice, or my endpoint is briefly down?
Most webhook delivery is at-least-once, not exactly-once, so duplicate deliveries can happen — usually from a retry after a network blip. Store each event's ID and check for duplicates before triggering anything irreversible. If your endpoint is briefly unavailable, keep a fallback channel such as email or Discord active so you're not relying on the webhook alone to catch every incident.
What's the difference between using webhooks and polling the monitoring API?
Webhooks push data to you the moment something happens, so there's no delay and no wasted requests checking for changes that haven't occurred. The monitoring API is better suited for pulling historical data, analytics, or configuration on demand — most teams end up using both together.
At the end of the day, webhook alerts aren't really about replacing Slack or email — they're about giving your systems the same information a human would get, but in a form your infrastructure can actually act on. Before you consider your setup done, run through this:
Wire it up once, secure it properly, and check it against your platform's real documented behaviour — and you'll spend a lot less time being the person who has to notice, decide, and act, and a lot more time trusting that your systems already have.
Automate certificate renewal alerts for SSL and domains with daily checks, named owners, and email, Slack, or webhook notifications.
Learn how to connect Slack downtime alerts and Discord webhooks to your monitoring tool for faster incident notifications and less alert noise.