Data-Driven Keyword Research: A Practical Guide to Finding Better Content Opportunities
Data-driven keyword research means using tools that analyse real search volume, competition, and performance data instead of guesswork or keyword stuffing, so you find topics your audience is actually searching for. The best approach combines search data with content performance history. That way, you're not just choosing keywords; you're choosing topics with evidence behind their potential to attract readers and rankings.
If you've ever published a blog post you were genuinely proud of, only to watch it sit on page four of Google gathering digital dust, you already know why this matters. I've been there. The content wasn't bad. It just wasn't built on any real evidence that people were searching for it. Let's fix that.
Why keyword research still matters for AI content
Here's something that surprises a lot of content creators: AI writing assistants have made it faster than ever to publish blog posts, but speed without direction just means you're wasting effort more efficiently. Google's algorithm still rewards content that matches what someone typed into the search bar. An AI tool can write you 2,000 words in minutes, but if those words answer a question nobody's asking, you've built a nice house on the wrong plot of land.
Think of keyword research as the map that tells you where to point your content energy. Without it, you're publishing on instinct, which occasionally works but mostly doesn't. With it, every post has a better shot at finding an audience before you've even hit publish.
This is honestly the number one reason I see blogs getting traffic but no conversions. They're ranking for something, sure, but it's the wrong something: vague terms with no commercial intent, or topics so broad they attract browsers rather than buyers. Data-driven keyword research fixes this by grounding your topic choices in what people actually want, not what you assume they want.
How data-driven keyword research finds real opportunities
So what does "data-driven" actually look like in practice? It's not one metric. It's several layers of evidence working together.
- Search volume and trend data show what people are typing into Google right now, not six months ago. Google Trends is useful here because it reveals seasonality, rising topics, and regional differences using a normalised interest scale rather than raw numbers.
- Competition analysis reveals the gaps: the spaces where smaller or newer sites can realistically break through, rather than going head-to-head with established giants over the same broad terms.
- Search intent signals tell you whether someone wants information, is ready to buy, or is trying to navigate to a specific brand. Get this wrong and even a well-optimised article will underperform because it's answering the wrong kind of question.
- UK-specific search data matters a lot. Phrasing and vocabulary often differ from US search volume. Think "trainers" versus "sneakers," or "holiday" versus "vacation." A UK ecommerce team comparing these terms in Keyword Planner might find they need entirely separate pages targeting each market, even when the product itself is identical.
- Tools like Ahrefs, Semrush, and Google Search Console give you the raw data, but the real skill is interpreting it correctly. Search Console shows impressions, clicks, click-through rate, and average position at the query level, which is gold if you know what to look for.
One detail that trips people up: search volume is an estimate, not a promise of traffic. Actual clicks depend on where you rank, what search features appear on the page, brand recognition, and even device type. Research from SparkToro and Datos found that over 58% of Google searches in the US ended without a click to any external result in 2024. That's a reminder that impressions and visibility matter just as much as the click itself.
Google has also said that around 15% of searches it sees each day are entirely new queries it hasn't encountered before. That's a good argument for keeping an eye on related searches, autocomplete suggestions, and "People Also Ask" boxes, rather than just relying on a static list of keywords you researched last year.
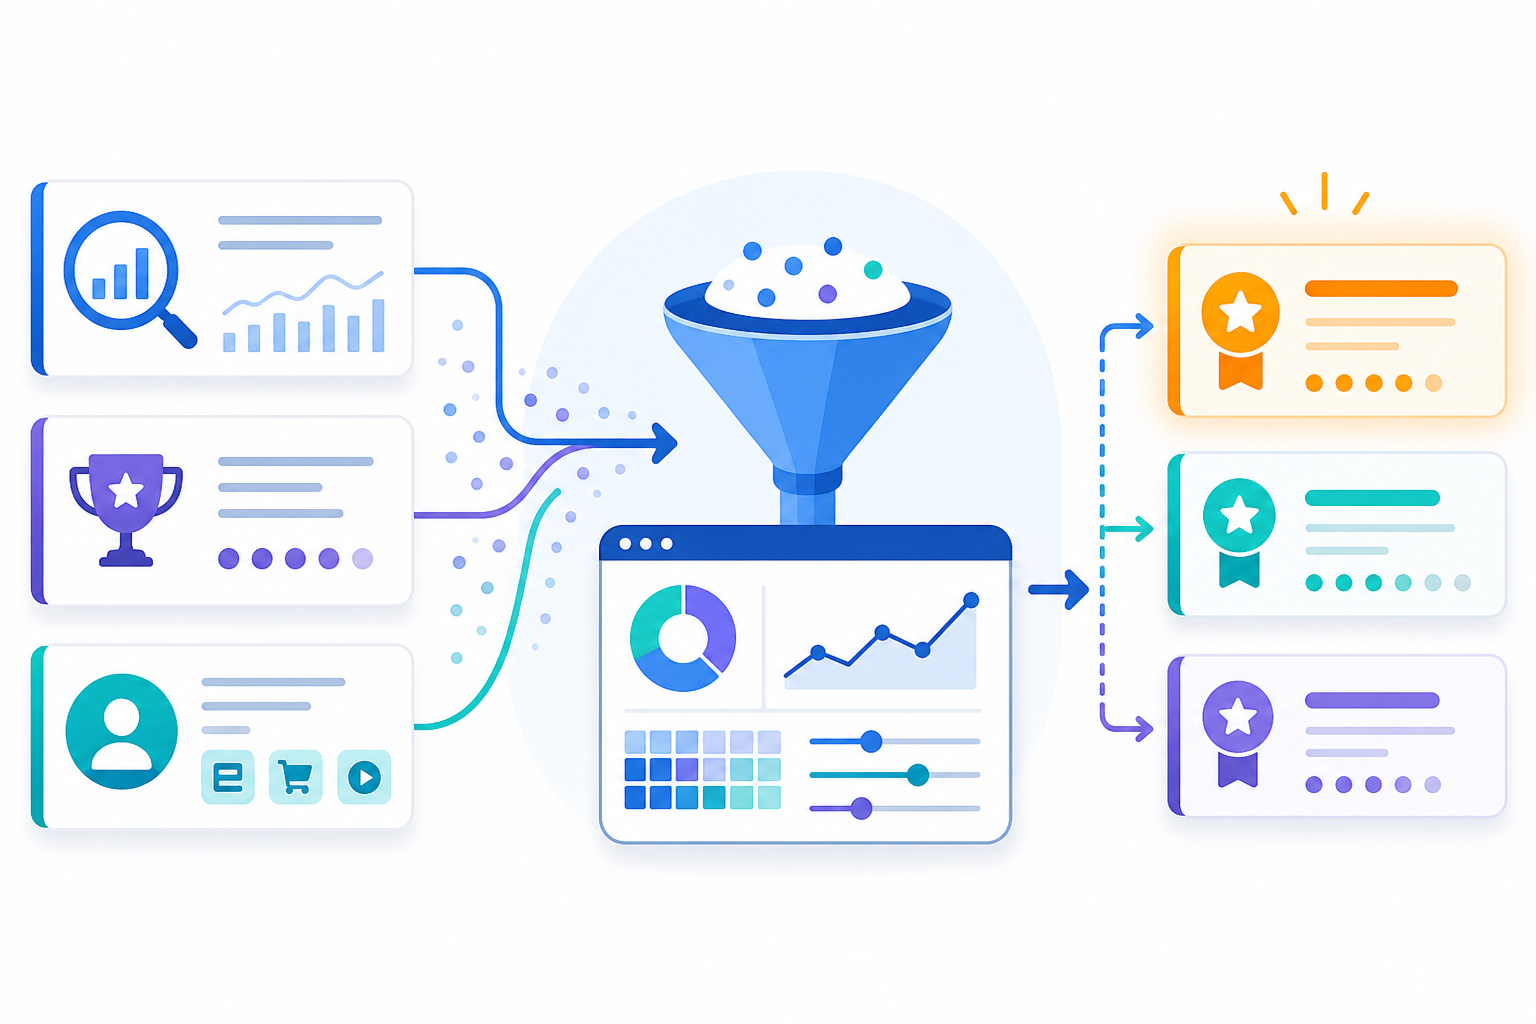
How to prioritise keywords using performance data
Once you've gathered your data, the next challenge is deciding what to actually write about first. This is where most creators either freeze up or default to picking whatever has the highest search volume, which is rarely the smartest move.
Here's the process I'd recommend instead:
- Rank keywords by a mix of factors: search volume, ranking difficulty, and business relevance, rather than volume alone. A keyword with modest search numbers but strong commercial intent often beats a huge, generic term with no clear buyer signal.
- Look at historical performance data. Which topics and content structures have driven traffic for you before? If long-form guides consistently outperform listicles on your site, that's a pattern worth repeating.
- Use quality scoring to identify overperforming articles and figure out why they worked. Was it the structure? The depth? The way it answered a specific question upfront? This is exactly the kind of insight Scribe's self-improving system is built to surface. It analyses quality scores and performance metrics from every published article, then replicates the patterns that actually worked while quietly discarding what didn't.
- Favour keywords where you can realistically compete, rather than chasing the highest-volume terms and hoping for the best. Here's a useful example: instead of writing a brand-new article for a competitive term, check if you already have a page ranking on page two for a related query. Google Search Console often reveals these near-miss opportunities: pages getting impressions but sitting at position 12 or 15. Improving that existing page's title, coverage, and internal links can be far more efficient than starting from zero.
- Let a self-improving content system learn from what's worked and adjust future keyword choices automatically. This is one of the biggest time-savers for teams trying to scale content without scaling headcount. The system gets smarter with every article you publish, rather than making you repeat the same manual analysis each time.
How to avoid keyword stuffing in AI-generated content
Now, a word of caution, because AI content generation makes it tempting to over-optimise, and Google has become very good at spotting when you have.
Google's helpful content systems reward clarity and usefulness over unnatural keyword repetition. If you're stuffing the same phrase into every other sentence, you're not fooling anyone, least of all an algorithm designed to understand context and evaluate whether content satisfies search intent.
A few principles that have served me well:
- Write for the reader first. If a sentence reads awkwardly because you've crammed a keyword into it, rewrite it. Every time.
- Use keyword variations and related terms naturally instead of repeating the exact same phrase throughout. Google understands synonyms and related concepts perfectly well. You don't need to say "data-driven keyword research" fifteen times to prove your article is about data-driven keyword research.
- Structure content around answering real reader questions, not hitting some arbitrary keyword quota. If your article genuinely covers the intent cluster behind a search term (definitions, examples, comparisons, next steps), you'll naturally include relevant language without forcing it.
- Quality scoring tools can flag over-optimised sections before you publish. I lean on this feature a lot. Catching an awkward, keyword-heavy paragraph before it goes live saves you from a much bigger headache later when readers find the content hard to follow.
Here's a real-world example of intent-matching done well: a cybersecurity publisher targeting the broad term "phishing" noticed that searchers weren't just looking for a definition. They wanted workplace examples, prevention steps, and training resources too. Rather than repeating "phishing" more often, the publisher built out sections covering that entire intent cluster. That's the difference between chasing a keyword and actually serving the person behind the search.
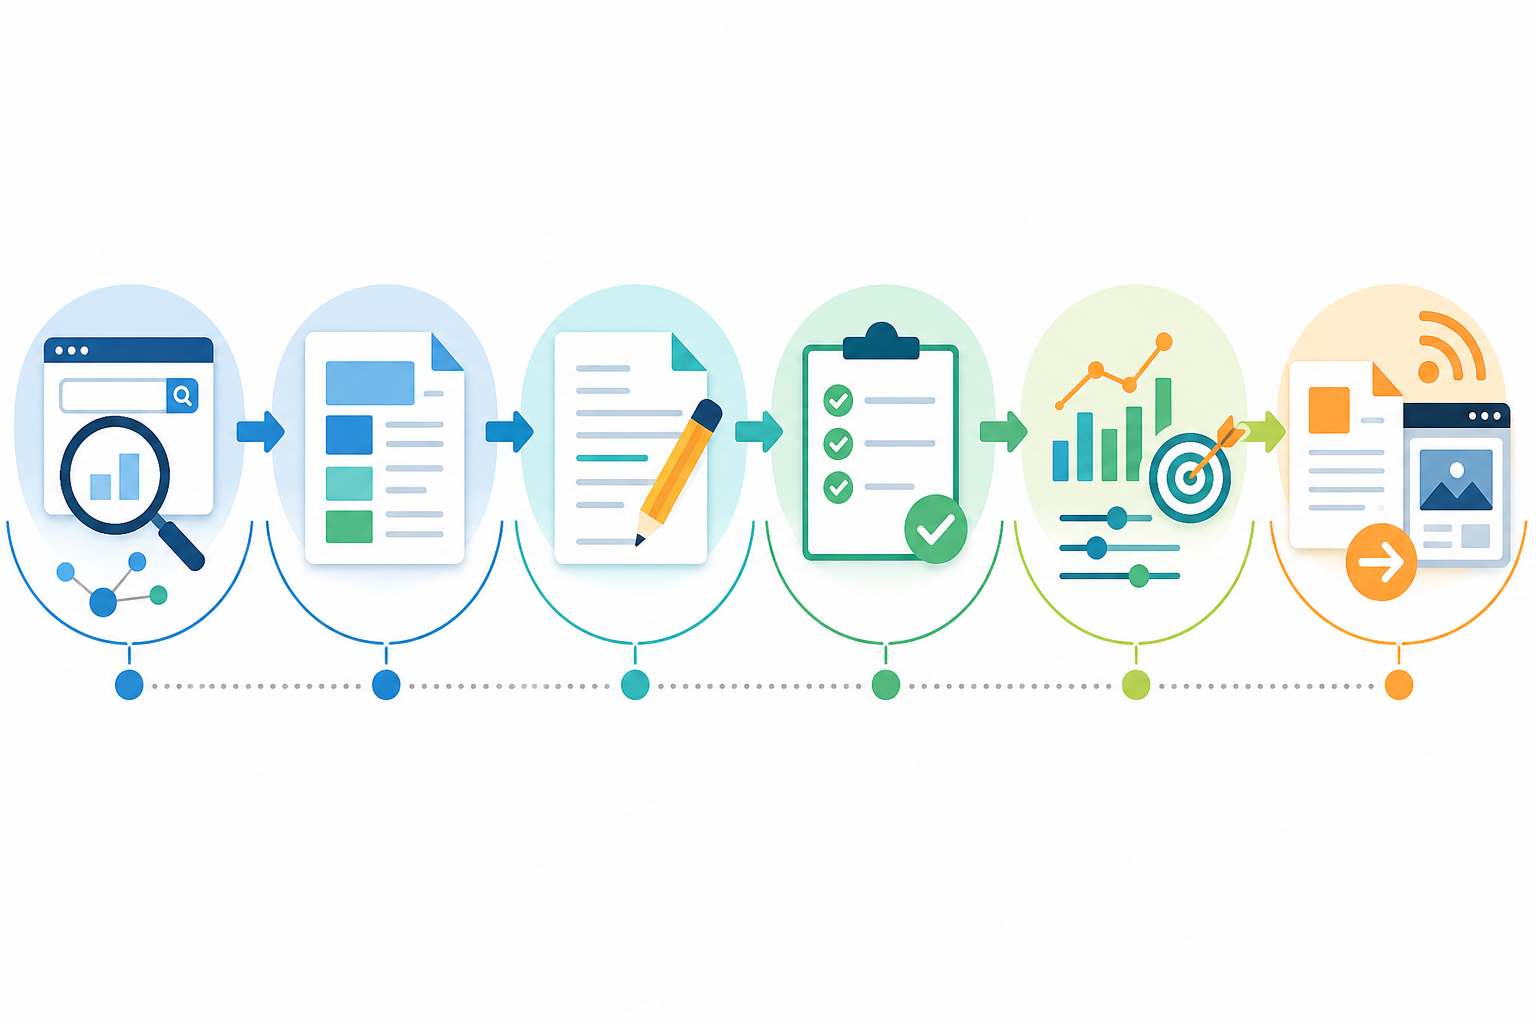
How to turn keywords into useful content
Once you've got your prioritised, natural keyword list, the fun part starts: actually building content people want to read.
- Group related keywords into one well-structured post rather than writing thin, repetitive pages for every slight variation. Long-tail queries often have lower individual volume but clearer intent, and evaluating the combined opportunity across a cluster of related searches is usually more efficient than treating each as a separate article.
- Build a clear content outline that answers the primary question upfront. Don't bury the lead. Readers, and Google, both reward content that gets to the point quickly, then backs it up with depth.
- Add supporting sections, examples, and visuals that make the topic genuinely useful, not just technically complete. This is where a lot of AI-generated content falls flat if it's not reviewed properly: it hits the right keywords but lacks the texture that makes a post actually worth reading.
- Use an AI writing assistant to draft quickly, but always review for accuracy and tone before publishing. This is exactly the balance Scribe is built around: generating complete, SEO-optimised blog posts, averaging over 2,000 words, with AI-generated images and diagrams, in about five minutes, so you get speed without sacrificing the quality checks that actually matter.
- Publish consistently. Automated publishing to platforms like WordPress, Shopify, Wix, or Webflow keeps your content momentum going without burning out your team. One-click publishing sounds like a small convenience until you're trying to hit 15 or 20 articles a month. Then it's the difference between sustainable content scaling and total burnout.
The results speak for themselves when this process is followed properly. One user of Scribe's automated publishing and quality scoring system reported a 340% increase in organic traffic over six months. That kind of number is only possible when keyword research, content structure, and publishing consistency are all working together rather than in isolation.
Frequently asked questions about data-driven keyword research
How do I find good keywords for blog posts?
Start with topics your audience genuinely searches for, then use a keyword research tool to check search volume and competition for the UK market specifically. Prioritise terms where the search intent matches the content you're planning to write: informational keywords for guides, commercial keywords for comparison or review posts.
What tools help with data-driven keyword research?
Popular options include Ahrefs, Semrush, and Google Search Console for raw search data. If you're producing content at scale, platforms with built-in data-driven optimisation, like Scribe, go a step further by analysing which keywords have historically driven traffic and engagement, then prioritising similar opportunities automatically.
How do I avoid keyword stuffing in AI content?
Focus on writing naturally for the reader rather than repeating an exact phrase a set number of times. Use synonyms and related terms, structure content around genuine questions, and check quality scores if your tool provides them. This can flag sections that read as over-optimised before you publish.
At the end of the day, data-driven keyword research isn't about outsmarting Google. It's about understanding your reader well enough that ranking well becomes a natural side effect of being genuinely useful. Get the research right, resist the urge to stuff, and let a self-improving system handle the heavy lifting of spotting patterns you might otherwise miss. That's how you scale content without scaling the guesswork.